Text-to-Image Generation Results with Baidu Wenxin
It is clear that the generation still has quite a few issues: the character's head remains less than ideal. The background is still quite good and the clothing is fine, but the face falls short.
What especially needs noting is that after switching to oil-painting style, the generated results — especially faces — remain hard to control; this is a common flaw of diffusion models. Sometimes it does produce acceptable images, and overall, cartoon-style faces are relatively acceptable.
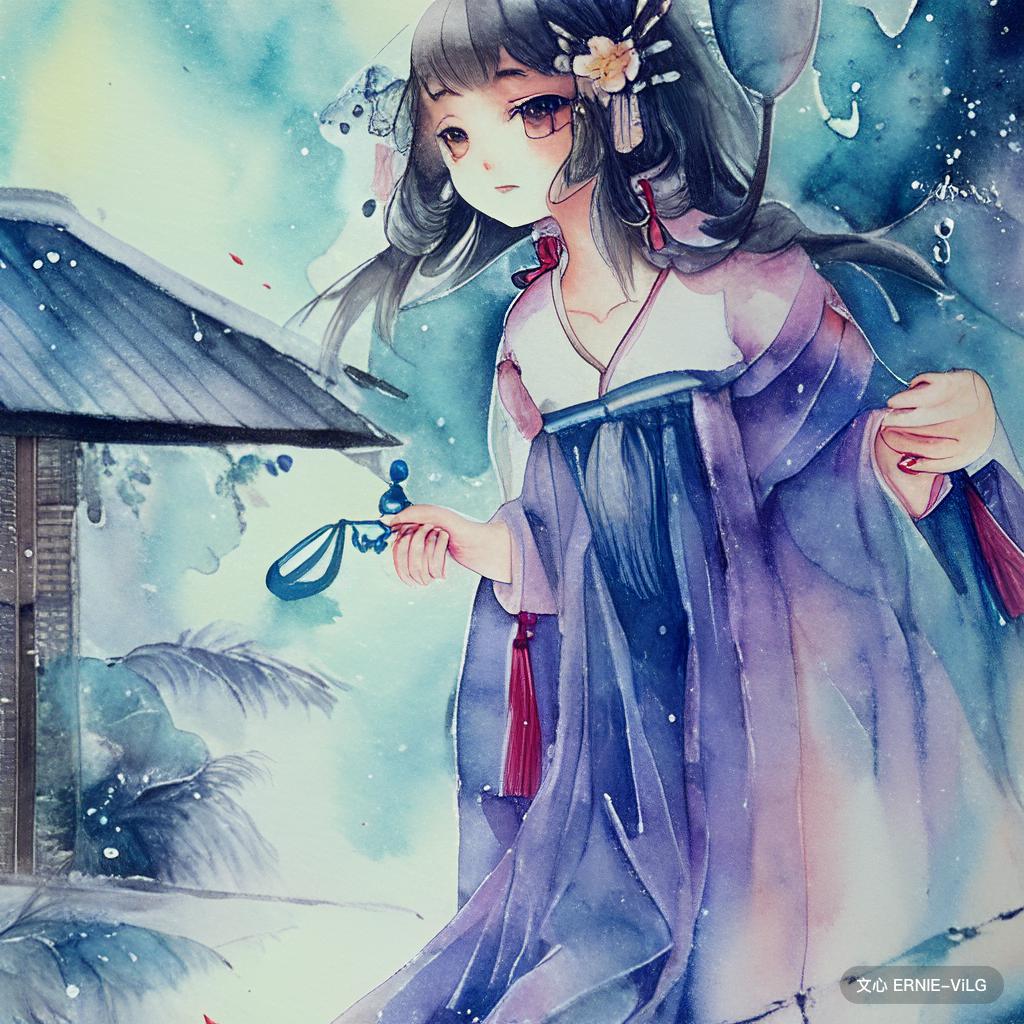
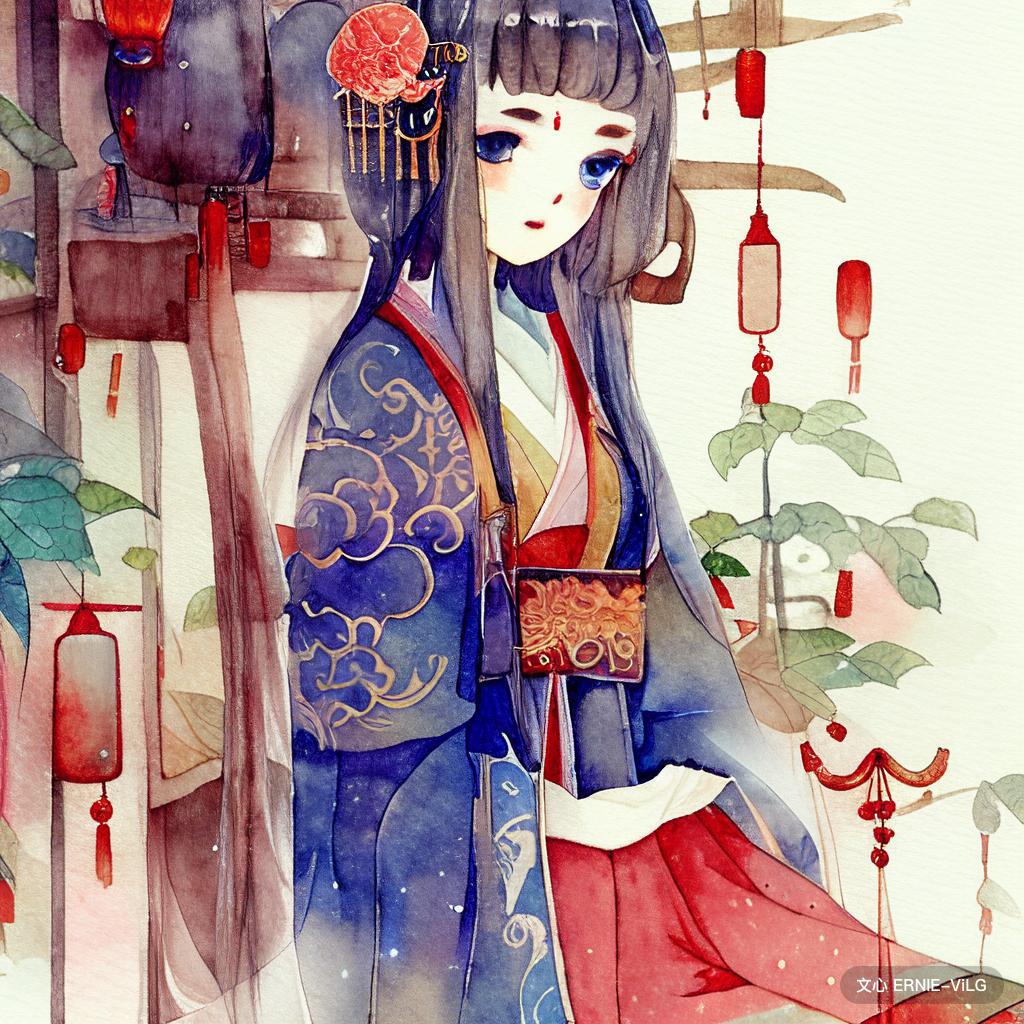
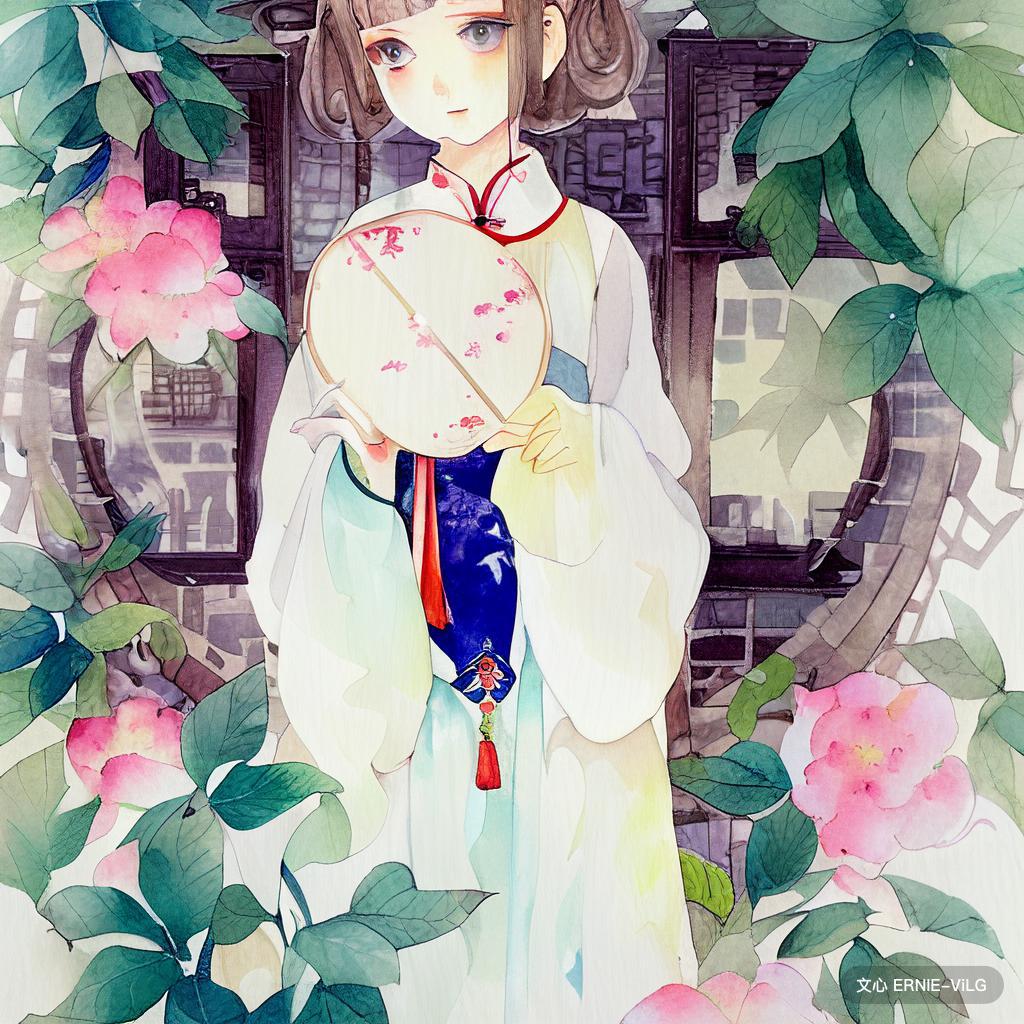
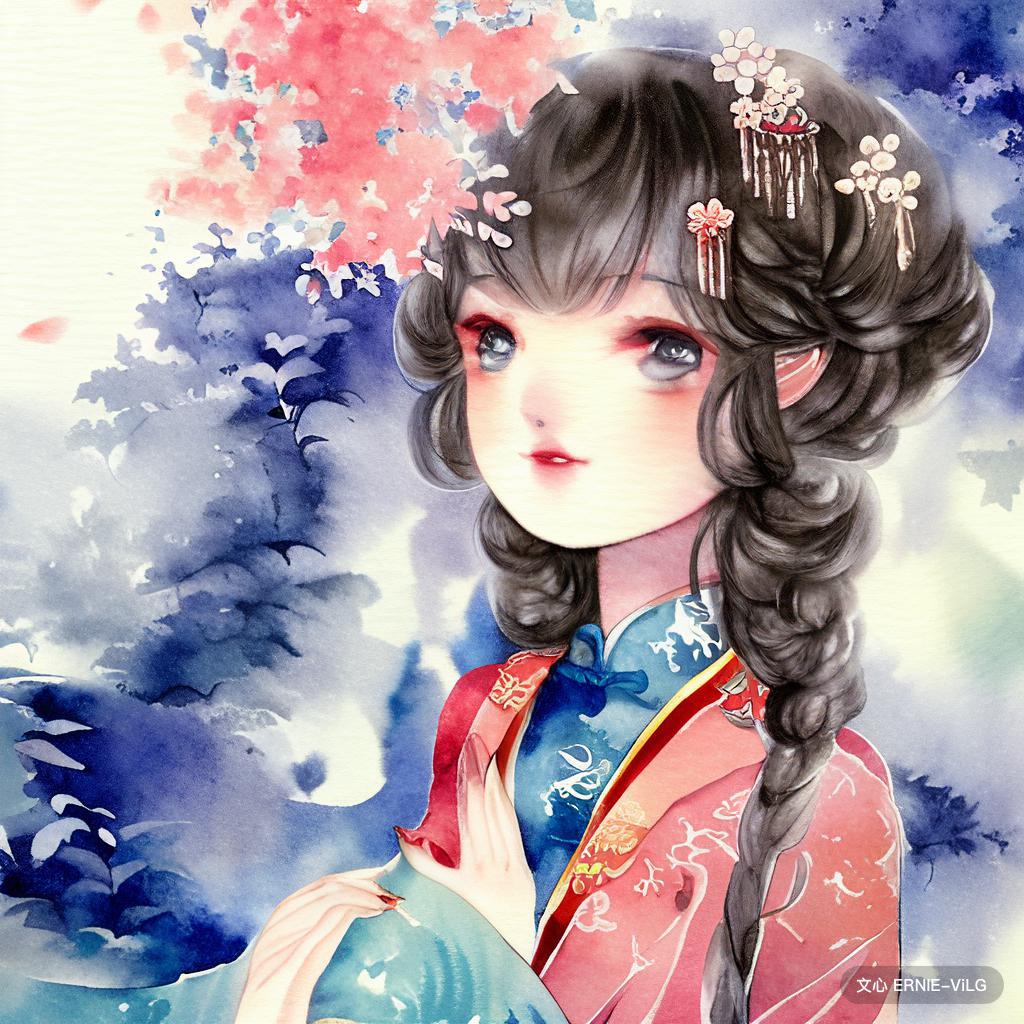
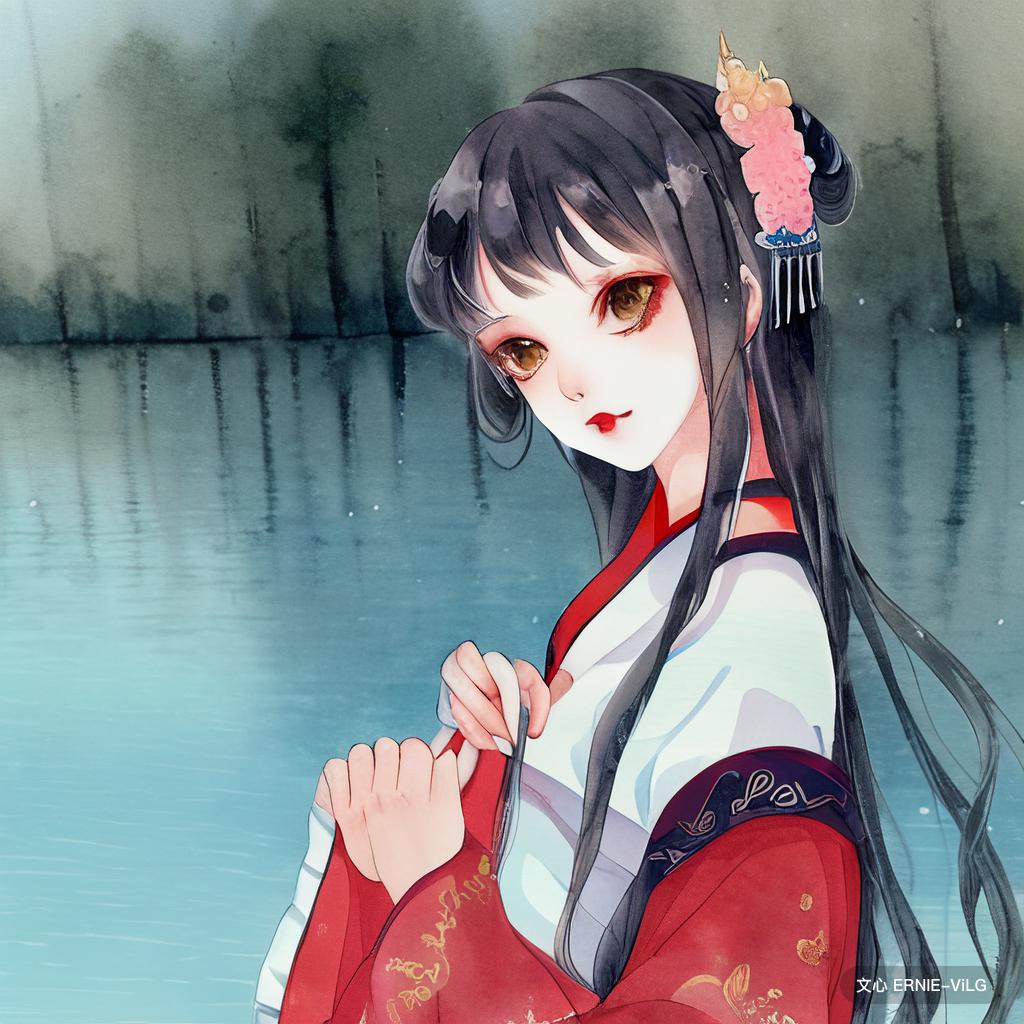
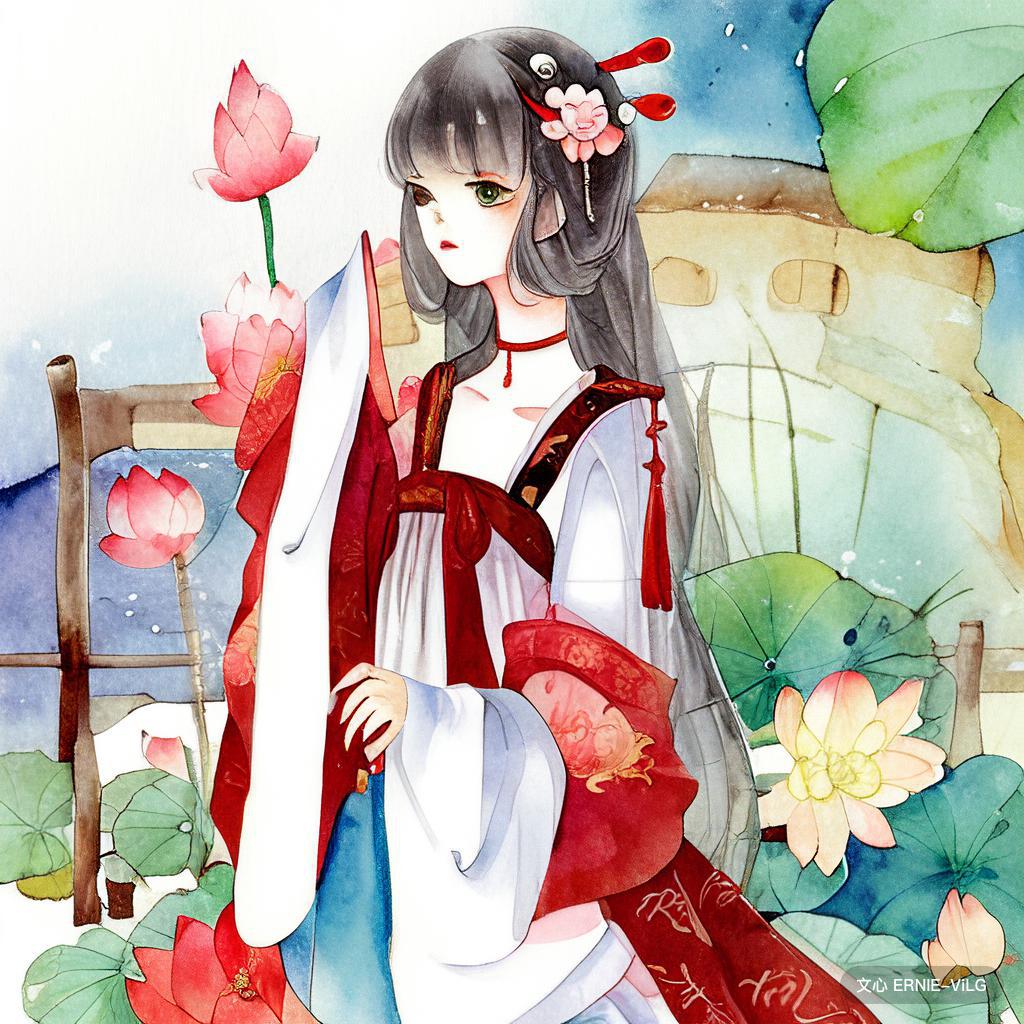
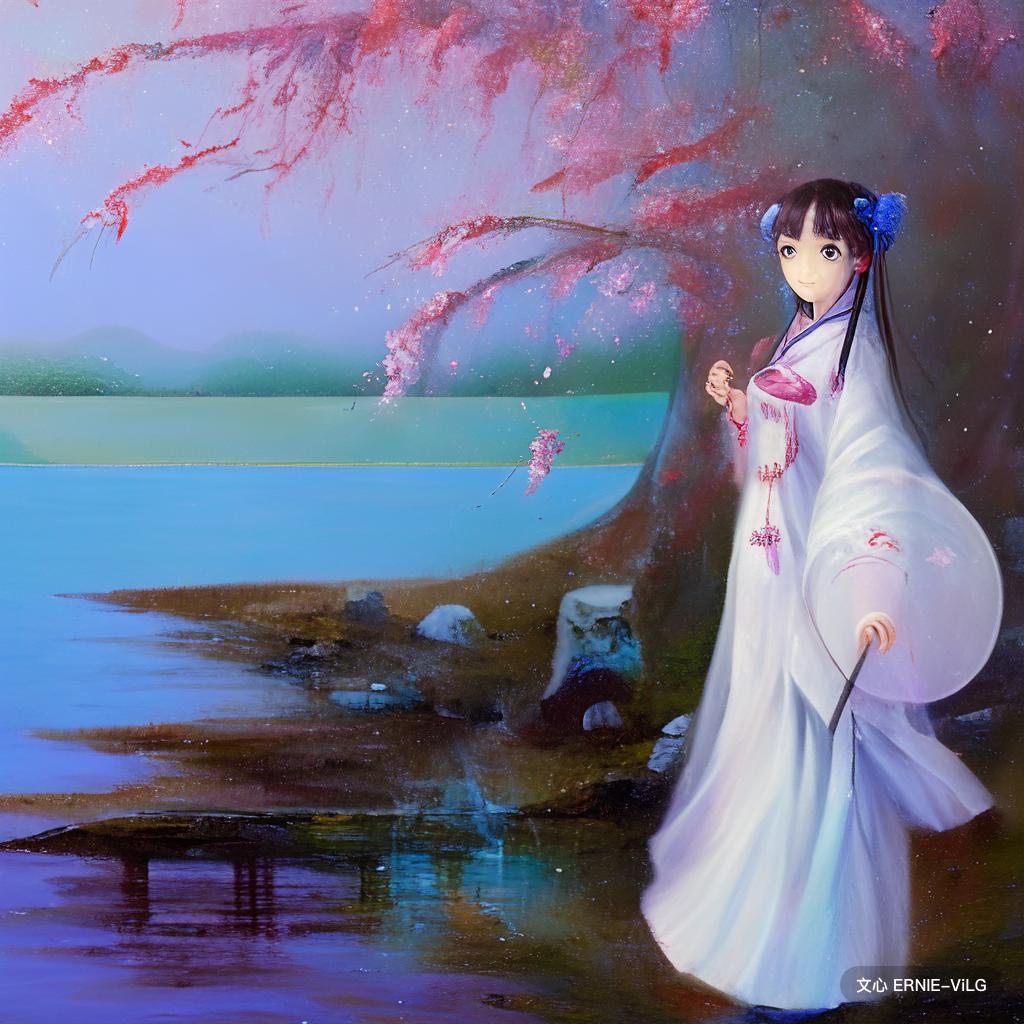
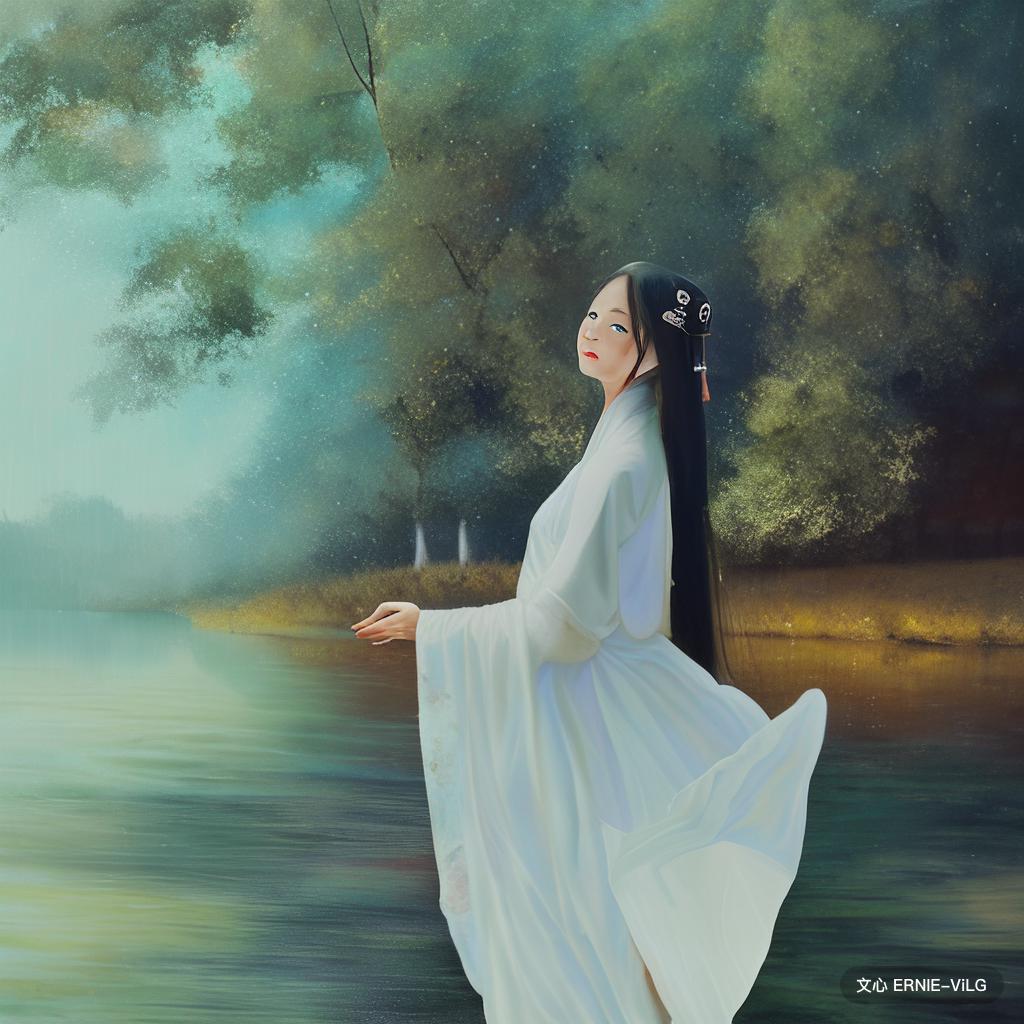
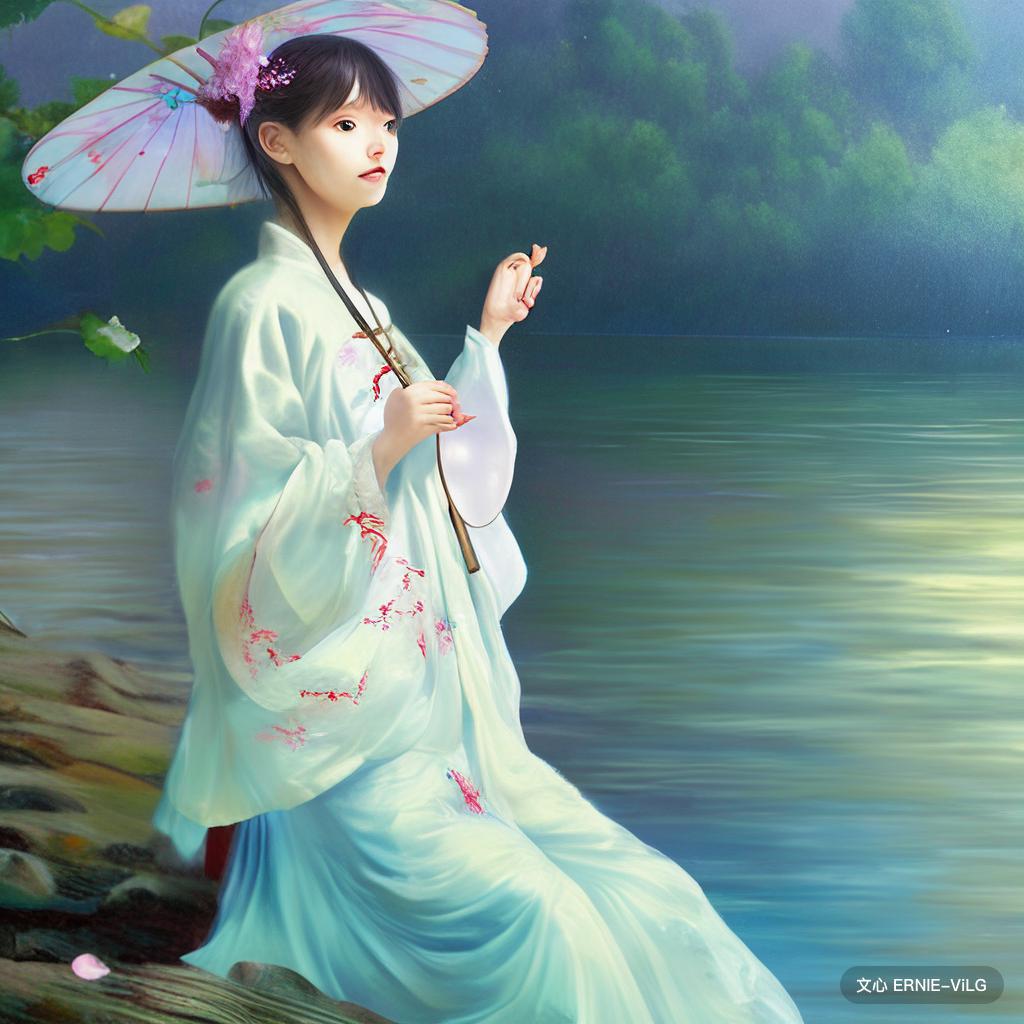 So among the keywords, I tried covering the face, but unfortunately Wenxin doesn't seem to recognize such instructions — though the results turned out surprisingly decent.
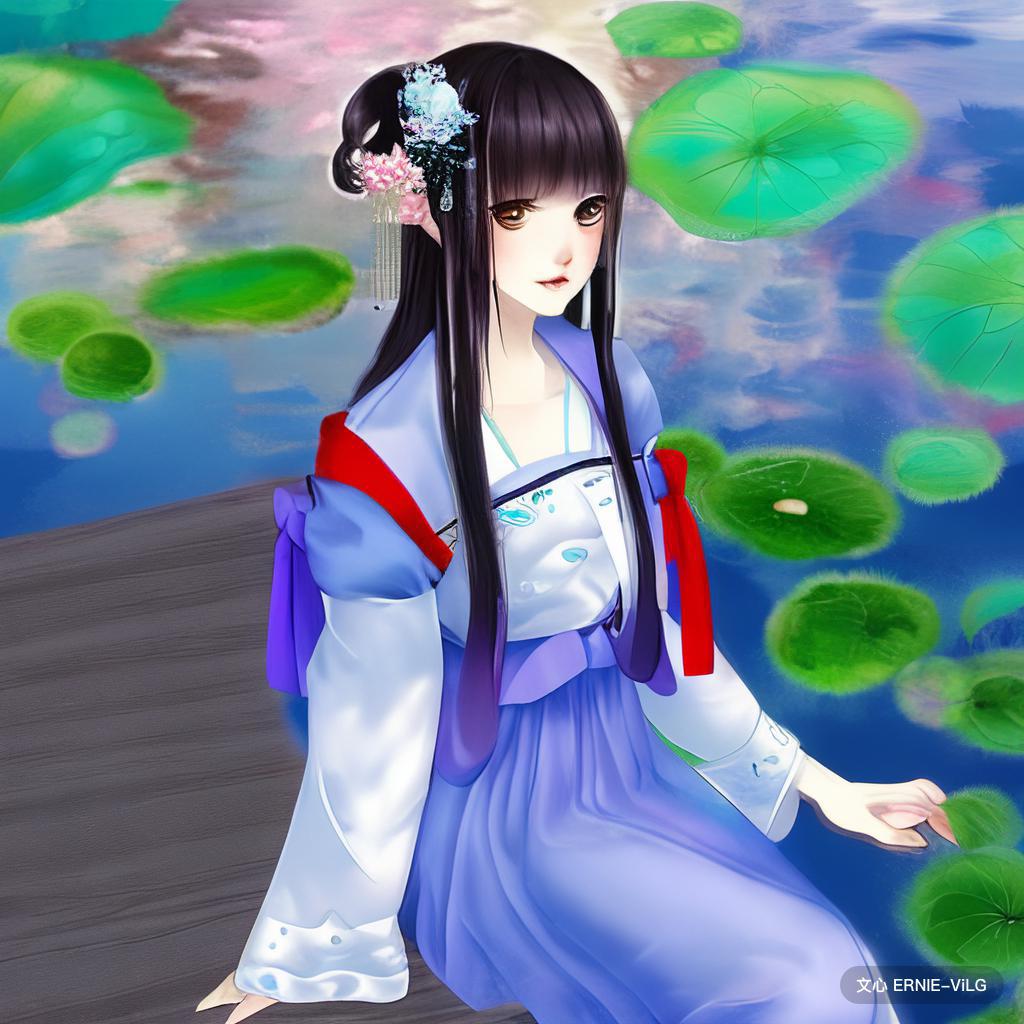 Currently Baidu Wenxin's text-to-image only offers watercolor, oil painting, chalk drawing, cartoon, crayon drawing, and children's drawing styles. Not yet able to try more interesting image generation — still pretty solid.
So among the keywords, I tried covering the face, but unfortunately Wenxin doesn't seem to recognize such instructions — though the results turned out surprisingly decent.
Currently Baidu Wenxin's text-to-image only offers watercolor, oil painting, chalk drawing, cartoon, crayon drawing, and children's drawing styles. Not yet able to try more interesting image generation — still pretty solid.